Unlock the Power of AI Gateway: Seamless Integration Strategies


The rapid proliferation of Artificial Intelligence across every conceivable industry has fundamentally reshaped the technological landscape, presenting both unprecedented opportunities and significant integration challenges. From sophisticated machine learning models predicting market trends to generative AI crafting compelling content, the power of AI is no longer a futuristic concept but a present-day imperative. However, harnessing this power effectively within complex enterprise architectures is far from a trivial undertaking. The sheer diversity of AI models, each with its unique APIs, authentication mechanisms, data formats, and performance characteristics, can quickly overwhelm development teams, leading to integration bottlenecks, increased operational costs, and compromised security postures. This intricate web of disparate AI services necessitates a robust, intelligent, and unified orchestrator – an AI Gateway.
At its core, an AI Gateway represents a sophisticated evolution of the traditional API Gateway, specifically engineered to address the unique complexities inherent in integrating and managing AI services. It acts as a single entry point for all AI-related requests, abstracting away the underlying intricacies of various AI models and vendors. This strategic architectural component not only simplifies the integration process for developers but also introduces a layer of centralized control, security, performance optimization, and cost management that is crucial for scalable AI adoption. As Large Language Models (LLMs) continue their meteoric rise, a specialized variant, the LLM Gateway, has emerged to tackle the distinct challenges posed by these highly dynamic and resource-intensive models, further emphasizing the need for intelligent AI orchestration.
This comprehensive article delves into the transformative potential of AI Gateway technology, exploring its foundational principles, its evolution from the established API Gateway, and its specialized manifestations like the LLM Gateway. We will dissect the myriad functionalities these gateways offer, from unified API interfaces and intelligent routing to advanced security protocols and detailed observability. Furthermore, we will examine strategic integration patterns within modern enterprise architectures, focusing on best practices for deployment, scalability, and governance. By the end, readers will possess a profound understanding of how to leverage AI Gateway solutions to unlock the full potential of AI, enabling seamless integration, enhancing operational efficiency, and securing a competitive edge in the AI-driven era.
1. Understanding the Landscape of AI Integration
The profound impact of Artificial Intelligence on virtually every sector of the global economy is undeniable. From healthcare diagnostics and financial fraud detection to personalized customer experiences and autonomous systems, AI is no longer a nascent technology but a mature and indispensable component of modern innovation. Enterprises are rapidly investing in AI capabilities, integrating diverse models into their core operations to drive efficiency, unlock new insights, and create differentiated products and services. However, this fervent adoption brings with it a complex tapestry of integration challenges that can significantly impede progress if not addressed strategically.
The AI Revolution and its Intrinsic Challenges for Developers
The current AI revolution is characterized by an explosion in the variety and sophistication of AI models. Developers today face a landscape populated by traditional machine learning algorithms (e.g., classification, regression), deep learning models (e.g., computer vision, natural language processing), and, most recently, the groundbreaking advent of generative AI and Large Language Models (LLMs). Each category, and often each specific model within a category, comes with its own set of technical nuances and operational requirements. This fragmentation creates substantial hurdles for development teams striving to embed AI seamlessly into their applications.
A primary challenge lies in the sheer diversity of AI model APIs. A developer wishing to integrate a sentiment analysis model from Vendor A, a speech-to-text model from Vendor B, and a custom image recognition model deployed in-house will encounter three distinct API specifications. These differences extend to data formats (JSON, Protobuf, custom binaries), authentication methods (API keys, OAuth tokens, IAM roles), error handling paradigms, and even the terminology used in their respective documentations. This lack of standardization forces developers to write bespoke integration code for each AI service, leading to bloated codebases, increased development time, and a steep learning curve for new team members.
Furthermore, managing the lifecycle of these integrations presents its own set of complexities. AI models are not static; they undergo continuous training, fine-tuning, and version updates. Each update can potentially introduce breaking changes to an API, necessitating revisions to integrated applications. Keeping track of model versions, ensuring backward compatibility, and coordinating updates across multiple applications become operational nightmares. Moreover, the dynamic nature of AI models means that performance characteristics, such as latency and throughput, can fluctuate, demanding adaptive strategies for request management.
Finally, the economic dimension of AI integration is a critical, often underestimated, challenge. Publicly available AI services from cloud providers typically operate on consumption-based pricing models, charging per request, per token, or per processing unit. Without a centralized mechanism to monitor, control, and optimize AI usage, organizations risk incurring exorbitant costs, especially as AI adoption scales. Manual tracking and individual budgeting for each integrated AI service are simply not sustainable or efficient in a large enterprise environment.
The Specific Challenges with Large Language Models (LLMs)
While general AI integration presents its own set of hurdles, Large Language Models (LLMs) introduce an entirely new stratum of complexity, necessitating specialized handling. LLMs, such as OpenAI's GPT series, Anthropic's Claude, or Google's Gemini, are powerful general-purpose models capable of understanding and generating human-like text, but their operational characteristics differ significantly from traditional AI models.
One of the most prominent challenges with LLMs is prompt engineering. The performance and utility of an LLM heavily depend on the quality and specificity of the input prompt. Crafting effective prompts requires iterative experimentation, and managing a repository of optimized prompts across different applications and use cases quickly becomes unwieldy. Storing prompts directly within application code couples the application logic tightly with the LLM's invocation, making updates cumbersome and preventing prompt-level A/B testing or versioning.
Context management is another critical aspect. LLMs operate with a "context window," a limited memory of previous interactions. For conversational AI or multi-turn applications, maintaining conversation history and ensuring that relevant past exchanges are fed back into subsequent prompts is crucial. Developers must manage this context manually, which can be complex, error-prone, and contributes to increased token usage and latency.
Rate limits and quotas imposed by LLM providers are often more stringent due to the high computational cost of these models. Applications need intelligent mechanisms to manage request volumes, implement retry logic, and handle backpressure gracefully to avoid service interruptions or outright rejections. Without a centralized system, individual applications might inadvertently hit limits, impacting user experience across the board.
Vendor lock-in is a significant concern. While a specific LLM might be optimal for a particular task today, the landscape is rapidly evolving. Organizations often desire the flexibility to switch between LLM providers (e.g., from OpenAI to Anthropic) or even incorporate fine-tuned internal models without rewriting substantial portions of their application code. Direct integration with a single vendor's API makes such transitions incredibly difficult and costly.
Furthermore, LLMs introduce unique security and safety considerations. The potential for prompt injection attacks, where malicious users manipulate the prompt to elicit unintended or harmful responses, is a constant threat. Ensuring that LLM outputs adhere to ethical guidelines and are free from bias or sensitive information requires advanced filtering and moderation capabilities, which are often beyond the scope of individual applications.
The amalgamation of these general AI integration challenges and the specific complexities of LLMs underscores an undeniable truth: relying on ad-hoc, point-to-point integrations for AI services is unsustainable and strategically unsound for any organization serious about leveraging AI at scale. The need for a unified, intelligent intermediary – a true AI Gateway – becomes not just a convenience, but an architectural imperative.
2. The Evolution from API Gateway to AI Gateway
To fully appreciate the transformative capabilities of an AI Gateway, it is essential to first understand its progenitor: the API Gateway. The API Gateway emerged as a critical architectural component in the era of microservices, addressing the challenges of managing numerous disparate backend services. The AI Gateway builds upon these foundational principles, extending them with specialized functionalities tailored for the unique demands of Artificial Intelligence services, especially those involving Large Language Models (LLMs).
What is an API Gateway? A Foundation of Modern Architectures
An API Gateway serves as a single entry point for all client requests, routing them to the appropriate backend services. In a microservices architecture, where an application is decomposed into many smaller, independently deployable services, clients would otherwise need to know the endpoints of potentially dozens or hundreds of individual services. This complexity is unmanageable. The API Gateway simplifies this by exposing a single, unified API to the client, acting as a facade for the underlying system.
The core functions of a traditional API Gateway are multifaceted and indispensable for modern distributed systems:
- Request Routing and Composition: The gateway intelligently routes incoming client requests to the correct backend microservice based on the request path, HTTP method, or other criteria. It can also compose responses by aggregating data from multiple services, providing a simpler interface to clients.
- Load Balancing: By distributing incoming traffic across multiple instances of a service, the API Gateway ensures high availability and optimal resource utilization, preventing any single service from becoming a bottleneck.
- Authentication and Authorization: It centralizes security checks, authenticating clients and authorizing their access to specific APIs before forwarding requests to backend services. This offloads security responsibilities from individual microservices, simplifying their development.
- Rate Limiting: To prevent abuse, denial-of-service attacks, and control resource consumption, gateways enforce rate limits on API calls, restricting the number of requests a client can make within a specified timeframe.
- Caching: Frequently accessed data or responses can be cached at the gateway level, reducing latency for clients and decreasing the load on backend services.
- Monitoring and Logging: The API Gateway acts as a central point for observing API traffic, collecting metrics on request volumes, error rates, and latency. It logs all API calls, providing a critical audit trail and diagnostic information.
- Traffic Management: Features like circuit breakers, retries, and timeouts can be implemented at the gateway level to improve system resilience and prevent cascading failures.
- Protocol Translation: It can translate between different protocols, allowing clients using one protocol (e.g., HTTP/1.1) to interact with backend services using another (e.g., gRPC).
The benefits of employing an API Gateway are substantial: it enhances security by centralizing access control, improves performance through caching and load balancing, simplifies client-side development by abstracting backend complexity, and fosters a more robust and scalable microservices ecosystem. It is a cornerstone for efficient and secure management of distributed applications.
Why Traditional API Gateways Fall Short for AI?
While the functionalities of a traditional API Gateway are robust and broadly applicable, they were not designed with the specific nuances and requirements of Artificial Intelligence services in mind. When confronted with the complexities of AI, particularly the dynamic and diverse nature of modern machine learning models and LLMs, the limitations of a standard API Gateway quickly become apparent.
One of the most significant shortcomings is the lack of AI-specific features. A traditional API Gateway is largely protocol-agnostic and data-agnostic beyond basic routing rules. It doesn't understand the semantic content of a prompt, the specific characteristics of an AI model's output, or the implications of token usage. It cannot natively manage prompts, versions of AI models, or intelligently route requests based on model capabilities, cost, or performance for AI-specific tasks.
Traditional gateways also struggle with the diversity of AI model APIs and data structures. As discussed, different AI models and vendors often present entirely disparate API contracts. A standard gateway simply forwards requests; it does not possess the intelligence to normalize these varied interfaces into a single, consistent format. This means developers would still be responsible for adapting their application's requests to each specific AI model's API, negating much of the abstraction benefit that an API Gateway typically provides.
AI-centric observability is another area where traditional gateways fall short. While they provide metrics like request counts and latency, they lack the granularity needed for AI services. For instance, they cannot track token usage for LLMs, monitor the cost per inference for specific models, or provide insights into model-specific error codes or inference durations. These metrics are crucial for cost optimization, performance tuning, and debugging AI-powered applications.
Furthermore, traditional gateways offer limited capabilities for intelligent routing based on AI-specific criteria. They might route based on simple load or URL paths, but they cannot dynamically select an AI model based on its current accuracy, cost-effectiveness for a given prompt, or real-time availability. The ability to switch between models seamlessly for A/B testing, fallback mechanisms, or cost efficiency is critical for AI workloads, but it's absent in conventional API Gateway designs.
Finally, while traditional gateways offer security, they are not inherently equipped to handle AI-specific security threats such as prompt injection, data poisoning, or ensuring the ethical use of generative AI. These require a deeper understanding of the AI payload and context.
Introducing the AI Gateway: An Intelligent Orchestrator for AI
The shortcomings of traditional API Gateway solutions in the context of advanced AI integration gave rise to the concept and necessity of the AI Gateway. An AI Gateway is not merely an API Gateway with a new name; it is an evolution that incorporates a deep understanding of AI workloads, offering specialized functionalities that directly address the unique challenges of integrating and managing AI services.
An AI Gateway serves as an intelligent intermediary layer that sits between client applications and various AI models (including traditional ML, deep learning, and especially LLMs). Its core purpose is to simplify, secure, optimize, and centralize the management of all AI interactions within an enterprise. It extends the fundamental principles of an API Gateway – such as routing, authentication, and rate limiting – with AI-specific intelligence and capabilities.
Key characteristics that define an AI Gateway include:
- Unified API for AI Models: It provides a consistent, standardized API interface for interacting with a multitude of diverse AI models from different vendors, abstracting away their individual quirks. This allows developers to consume AI services without needing to understand each model's specific API.
- Intelligent AI Routing: Beyond simple load balancing, an AI Gateway can dynamically route requests to the most appropriate AI model based on criteria such as cost, latency, model performance, specific prompt requirements, or even A/B testing configurations.
- Prompt Management and Orchestration: For LLMs, it offers dedicated features to store, version, and manage prompts, enabling prompt chaining, A/B testing of prompts, and the encapsulation of prompts into reusable APIs.
- AI-Specific Observability and Cost Management: It tracks metrics relevant to AI, such as token usage, inference costs, model-specific error rates, and latency per model, providing granular insights for optimization and billing.
- Enhanced AI Security: It implements security measures tailored for AI, including input validation, output sanitization, and protection against prompt injection attacks, safeguarding both the models and the applications consuming them.
In essence, an AI Gateway acts as a strategic control plane for an organization's AI ecosystem. It transforms a chaotic mesh of point-to-point AI integrations into a streamlined, secure, and highly manageable system. By centralizing AI governance, it significantly reduces development overhead, accelerates AI adoption, and ensures that organizations can leverage the full power of AI, including the most advanced LLMs, without succumbing to complexity or security risks. Products like ApiPark exemplify this evolution, offering an all-in-one AI Gateway and API management platform designed to simplify the integration and deployment of AI and REST services, particularly focusing on unifying AI model invocation and management.
3. Deep Dive into AI Gateway Functionalities
The true power of an AI Gateway lies in its specialized functionalities, which extend far beyond the capabilities of a traditional API Gateway. These features are meticulously crafted to address the unique complexities of integrating, managing, and optimizing AI services. Let's explore these capabilities in detail, understanding how they collectively streamline the adoption of AI within an enterprise architecture.
Unified API for Diverse AI Models
One of the most compelling advantages of an AI Gateway is its ability to present a unified, consistent API interface to client applications, regardless of the underlying AI model or vendor. In a world where AI providers like OpenAI, Anthropic, Google Gemini, and countless others offer their services through proprietary APIs, developers face a constant challenge of adapting their code for each new integration. The AI Gateway acts as an abstraction layer, normalizing these disparate interfaces.
This standardization means that an application can invoke a sentiment analysis API, for instance, without needing to know if it's powered by an in-house TensorFlow model, an AWS Comprehend service, or a fine-tuned LLM. The gateway translates the standardized request from the application into the specific format required by the chosen backend AI model and then translates the model's response back into a consistent format for the application. This significantly simplifies integration for developers, allowing them to focus on application logic rather than wrestling with varied AI provider SDKs and data schemas. It dramatically reduces development time and maintenance costs, as changes in AI models or providers are managed at the gateway level, insulating upstream applications from breaking changes. ApiPark specifically highlights this capability, offering a unified API format for AI invocation, ensuring that changes in underlying AI models or prompts do not affect the application or microservices.
Intelligent Request Routing and Load Balancing
Beyond simply directing traffic, an AI Gateway implements intelligent routing strategies that are crucial for optimizing AI workloads. This intelligence allows the gateway to make real-time decisions about which AI model should process a given request, based on a sophisticated set of criteria:
- Cost: The gateway can be configured to route requests to the most cost-effective model available for a specific task, dynamically switching between providers based on real-time pricing or pre-defined cost thresholds.
- Latency: For applications where response time is critical, the gateway can route requests to the model instance or provider that is currently exhibiting the lowest latency.
- Reliability/Availability: If a particular AI model or provider is experiencing issues or downtime, the gateway can automatically failover to a healthy alternative, ensuring continuous service delivery.
- Model Capability: Requests can be routed based on the specific capabilities required. For example, a complex reasoning task might go to a more powerful LLM, while a simple classification task goes to a smaller, faster, and cheaper model.
- Business Logic: Routing can be based on custom business rules, such as routing high-priority requests to premium models or requests from specific user segments to tailored AI experiences.
- A/B Testing: The gateway can intelligently split traffic to different models or model versions to perform A/B tests, allowing developers to compare performance, accuracy, and cost in a controlled environment.
This dynamic routing capability is paramount for fault tolerance, performance optimization, and cost efficiency in diverse AI landscapes.
Advanced Authentication and Authorization
Security is paramount when dealing with AI services, especially given the sensitive nature of data often processed by these models. An AI Gateway centralizes authentication and authorization, acting as a robust security enforcement point for all AI interactions.
- Centralized Security Policies: Instead of configuring security individually for each AI model or application, the gateway allows for the definition and enforcement of comprehensive security policies at a single point. This includes API key management, OAuth 2.0 flows, JWT validation, and integration with enterprise identity providers (IdP).
- Granular Access Control: The gateway can implement fine-grained authorization, ensuring that only authenticated and authorized users or applications can access specific AI models or features. For example, certain teams might only have access to specific generative AI models, while others have access to sensitive analytical models.
- Subscription Approval: Some advanced AI Gateway solutions, such as ApiPark, incorporate subscription approval features. This means that callers must explicitly subscribe to an API and await administrator approval before they can invoke it, adding an extra layer of control and preventing unauthorized API calls and potential data breaches, which is crucial for sensitive AI services.
Rate Limiting and Quota Management
To prevent abuse, manage costs, and ensure fair resource allocation, an AI Gateway implements sophisticated rate limiting and quota management mechanisms.
- Flexible Rate Limits: Limits can be applied at various levels: per user, per application, per team, or even per specific AI model. This allows for precise control over resource consumption and prevents any single client from monopolizing AI services.
- Quota Enforcement: Beyond simple rate limiting, quotas define the total amount of usage allowed over a longer period (e.g., daily token limits for an LLM). The gateway tracks consumption against these quotas and can block requests once a limit is reached.
- Dynamic Adjustments: Rate limits and quotas can be dynamically adjusted based on real-time traffic, system load, or business requirements, providing adaptive resource management.
Prompt Engineering and Management
For Large Language Models, prompt engineering is a critical discipline. An AI Gateway elevates prompt management from a scattered, application-level concern to a centralized, governable process.
- Prompt Storage and Versioning: The gateway can act as a repository for prompts, allowing developers to store, categorize, and version different prompt templates. This ensures consistency, enables easy rollback to previous prompt versions, and facilitates collaboration.
- Encapsulation into REST API: A powerful feature, exemplified by ApiPark, is the ability to quickly combine AI models with custom prompts to create new, reusable APIs. For instance, a complex prompt designed for sentiment analysis or data extraction can be encapsulated into a simple REST API call. This means applications don't need to construct complex prompts; they just call a specific API, simplifying integration and making prompts reusable and governable.
- A/B Testing Prompts: By routing a percentage of traffic to different prompt versions, the gateway enables controlled experimentation to determine which prompt yields the best results (e.g., accuracy, creativity, conciseness) for a given LLM.
Cost Optimization and Tracking
AI services, especially LLMs, can be expensive. An AI Gateway provides the necessary visibility and control to manage and optimize these costs effectively.
- Granular Usage Tracking: It meticulously tracks usage metrics, such as the number of requests, the total tokens consumed (for LLMs), and the processing units utilized, often breaking it down by user, application, project, or department.
- Cost Allocation: With detailed usage data, organizations can accurately allocate AI costs to specific business units or projects, fostering accountability and enabling more precise budgeting.
- Cost-Aware Routing: As mentioned in intelligent routing, the gateway can actively make decisions to choose the most cost-effective model for a given task, contributing directly to cost savings.
- ApiPark specifically notes its capability for unified management for authentication and cost tracking across a variety of AI models, demonstrating its commitment to financial visibility.
Observability: Monitoring, Logging, and Analytics
Comprehensive observability is vital for maintaining the health, performance, and security of AI-powered applications. An AI Gateway provides a centralized hub for monitoring, logging, and analytics tailored for AI workloads.
- Real-time Metrics: It collects and exposes key performance indicators (KPIs) in real-time, including latency (per model, per request), error rates, throughput, token usage, and resource consumption. These metrics are invaluable for identifying bottlenecks and performance degradation.
- Comprehensive Logging: Every API call, including the request payload, response, and relevant metadata (e.g., model chosen, tokens used, cost incurred), is meticulously logged. This detailed logging, a feature ApiPark provides, is essential for debugging issues, auditing compliance, and ensuring data security. It allows businesses to quickly trace and troubleshoot issues in API calls, ensuring system stability.
- Powerful Data Analysis: Beyond raw logs, the gateway can provide aggregated data analysis. ApiPark explicitly states its ability to analyze historical call data to display long-term trends and performance changes. This predictive analytics helps businesses with preventive maintenance, identifying potential issues before they impact users, and gaining insights into AI usage patterns and model performance over time.
Caching AI Responses
For AI services that produce deterministic or frequently requested outputs, caching at the AI Gateway level can dramatically improve performance and reduce costs.
- Reduced Latency: By serving responses directly from the cache, the gateway bypasses the need to invoke the backend AI model, leading to significantly faster response times for clients.
- Cost Savings: Each cache hit means one less call to an often-paid AI service, directly translating into cost reductions, especially for high-volume requests to LLMs.
- Cache Invalidation Strategies: The gateway provides mechanisms to invalidate cached responses when the underlying AI model updates or when the source data changes, ensuring data freshness and accuracy.
Security Enhancements for AI
The AI Gateway introduces specific security enhancements to protect against AI-specific vulnerabilities.
- Data Sanitization and Input Validation: It can inspect incoming requests to validate input formats and sanitize payloads, mitigating risks like SQL injection or other data manipulation attacks that might inadvertently influence AI model behavior.
- Protection Against Prompt Injection: For LLMs, the gateway can implement filters and rules to detect and mitigate prompt injection attempts, where malicious users try to manipulate the LLM's instructions.
- Output Moderation and Filtering: The gateway can analyze AI model outputs to filter out harmful, biased, or inappropriate content before it reaches the end-user, ensuring responsible AI deployment.
- Compliance (GDPR, HIPAA): By centralizing data flow and enforcing security policies, the gateway helps organizations maintain compliance with various data privacy and security regulations, especially when sensitive data is processed by AI models.
In summary, the sophisticated functionalities of an AI Gateway are engineered to transform the complex and fragmented world of AI integration into a streamlined, secure, cost-effective, and highly observable ecosystem. By acting as an intelligent orchestration layer, it empowers organizations to unlock the full potential of AI, from traditional models to cutting-edge LLMs, with unprecedented ease and confidence.
APIPark is a high-performance AI gateway that allows you to securely access the most comprehensive LLM APIs globally on the APIPark platform, including OpenAI, Anthropic, Mistral, Llama2, Google Gemini, and more.Try APIPark now! 👇👇👇
4. The Specialized Role of LLM Gateway
While the broader AI Gateway encompasses the management of all types of AI models, the advent and rapid evolution of Large Language Models (LLMs) have necessitated the emergence of a specialized variant: the LLM Gateway. An LLM Gateway extends the core functionalities of an AI Gateway with features uniquely tailored to address the distinct characteristics and challenges presented by these powerful, yet complex, generative models. Understanding this specialization is crucial for organizations heavily investing in LLM-powered applications.
Why LLMs Need a Dedicated Gateway: Unpacking Unique Characteristics
LLMs differ fundamentally from traditional AI models in several critical aspects, and these differences directly translate into specific operational and architectural requirements that a generic AI Gateway might not fully satisfy.
- Token Limits and Context Window: LLMs process information in "tokens" (words or sub-words). Each API call has a maximum input and output token limit, known as the context window. Managing this limit, especially in conversational scenarios where context needs to be preserved over multiple turns, is a complex task. An LLM Gateway specifically addresses this by tracking token usage and helping to manage the conversation history within these constraints.
- Complex, Generative Outputs: Unlike traditional models that might output a classification label or a numerical prediction, LLMs generate free-form text. Parsing, validating, and structuring these diverse outputs for consumption by applications requires specialized handling.
- Hallucination Risks: LLMs can sometimes "hallucinate," generating factually incorrect but syntactically plausible information. An LLM Gateway can incorporate guardrails and validation layers to mitigate this risk, ensuring more reliable outputs.
- Prompt Engineering Sensitivity: The performance of an LLM is highly sensitive to the quality and structure of the input prompt. An LLM Gateway provides robust tools for managing, versioning, and optimizing these prompts.
- Statefulness in Conversations: While individual LLM API calls are typically stateless, real-world conversational applications require statefulness. The gateway becomes the ideal place to manage this conversation history, insulating applications from the complexities of storing and retrieving context for each turn.
- Vendor Landscape and Rapid Evolution: The LLM market is highly dynamic, with new models and providers emerging frequently. An LLM Gateway provides the flexibility to abstract away vendor-specific APIs, allowing seamless switching between models like OpenAI, Anthropic, or Google Gemini without application changes.
These unique characteristics underscore why an LLM Gateway is not merely an optional add-on but an essential component for any enterprise serious about building robust, scalable, and secure applications powered by Large Language Models.
Key LLM Gateway Features
Building upon the foundation of a general AI Gateway, an LLM Gateway introduces several specialized features designed to optimize the performance, cost-efficiency, security, and developer experience for LLM integrations:
- Context Management and Conversation History:
- Intelligent History Storage: The gateway manages and stores conversation history for multi-turn interactions, ensuring that relevant previous exchanges are included in subsequent LLM prompts without applications having to manually track state.
- Context Window Optimization: It can intelligently summarize or truncate conversation history to fit within the LLM's token limit, prioritizing the most relevant information to maximize context effectiveness while minimizing token usage.
- Session Management: The gateway maintains user sessions, linking multiple LLM calls to a continuous conversation thread, which is crucial for building sophisticated conversational AI agents.
- Token Management and Cost Control:
- Precise Token Tracking: The gateway accurately tracks input and output token usage for every LLM call, providing granular data for cost allocation and consumption monitoring.
- Token Limit Enforcement: It enforces pre-defined token limits per user, application, or session, preventing excessive usage and ensuring adherence to budgetary constraints.
- Proactive Cost Alerts: The gateway can trigger alerts when token usage approaches predefined thresholds, allowing for proactive intervention before costs spiral out of control.
- Prompt Orchestration and Advanced Prompt Engineering:
- Dynamic Prompt Chaining: For complex tasks, the gateway can orchestrate a sequence of LLM calls, chaining multiple prompts together to achieve a desired outcome. This enables breaking down large problems into manageable steps for the LLM.
- Conditional Prompting: It can dynamically select and modify prompts based on user input, application state, or external data, allowing for highly adaptive and personalized LLM interactions.
- Prompt Templating and Versioning: Beyond basic storage, the gateway offers advanced templating capabilities, allowing developers to define reusable prompt structures with placeholders, and manage multiple versions of these templates.
- As highlighted by ApiPark, the capability to encapsulate custom prompts with AI models into new REST APIs simplifies prompt management and promotes reusability across teams.
- Response Parsing and Transformation:
- Structured Output Generation: While LLMs generate free-form text, applications often require structured data (e.g., JSON). The gateway can post-process LLM outputs, attempting to parse them into a desired format and handling cases where the LLM's output deviates from the expected structure.
- Output Validation and Correction: It can validate the LLM's generated response against schemas or business rules, potentially re-prompting the LLM or applying corrective logic if the output is invalid or incomplete.
- Sentiment and Tone Analysis of Output: Advanced gateways can even apply secondary AI models to analyze the sentiment or tone of the LLM's output before it reaches the user, adding an extra layer of control.
- Guardrails and Safety Filters:
- Harmful Content Detection: The gateway can integrate with content moderation APIs or use its own models to filter out harmful, toxic, or biased outputs generated by the LLM, ensuring responsible AI deployment.
- PII Redaction/Masking: For sensitive applications, the gateway can automatically detect and redact Personally Identifiable Information (PII) from both input prompts and LLM outputs, enhancing data privacy and compliance.
- Controllable Boundaries: It establishes clear boundaries for LLM behavior, preventing it from generating responses that are outside the scope of its intended use or that violate ethical guidelines.
- Model Agnostic Interaction and Provider Flexibility:
- Unified LLM API: Similar to the general AI Gateway, an LLM Gateway provides a single, consistent API for interacting with various LLM providers, abstracting away their unique endpoints, authentication, and request/response formats.
- Seamless Model Switching: This abstraction allows applications to switch between different LLM models (e.g., GPT-4 to Claude 3) or even between cloud and on-premise LLMs with minimal to no code changes, mitigating vendor lock-in risks.
- Fine-tuning and Custom Model Integration:
- Management of Fine-tuned Models: The gateway can manage access to custom fine-tuned LLMs deployed internally or externally, providing the same unified interface as for public models.
- Version Control for Custom Models: It supports versioning of fine-tuned models, allowing for A/B testing and controlled rollouts of new iterations.
- Agentic Workflows and Tool Integration:
- Orchestrating Complex Tasks: Modern LLM applications often involve "agents" that use LLMs to reason and then call external tools or APIs (e.g., search engines, databases) to perform tasks. An LLM Gateway can be configured to orchestrate these multi-step, agentic workflows, managing the calls to the LLM and the external tools.
- Function Calling Proxy: It can act as a proxy for LLM function calling, where the LLM is prompted to decide which external function to call, and the gateway facilitates that call and returns the result to the LLM for further processing.
In essence, an LLM Gateway refines the concept of an AI Gateway by zeroing in on the specific operational nuances of Large Language Models. It empowers developers to build sophisticated, robust, and responsible LLM-powered applications by managing complexity, enhancing control, and optimizing the interaction with these transformative AI models. It acts as the intelligent control plane, ensuring that the immense power of LLMs can be wielded effectively and safely across the enterprise.
5. Strategic Integration of AI Gateways in Enterprise Architecture
Integrating an AI Gateway strategically into an enterprise architecture is not merely about plugging in a new component; it's about fundamentally rethinking how AI services are consumed, managed, and governed across the organization. Its placement and configuration have profound implications for scalability, security, development velocity, and ultimately, the success of AI initiatives.
Deployment Models: Flexibility for Every Enterprise
The choice of deployment model for an AI Gateway depends on an organization's existing infrastructure, security requirements, compliance needs, and operational preferences.
- On-Premise Deployment:
- Control and Security: Enterprises with strict data residency requirements or highly sensitive data often opt for on-premise deployment. This model offers maximum control over the infrastructure, ensuring that all AI traffic and data remain within the company's private network, which is critical for meeting stringent compliance standards (e.g., HIPAA, GDPR, PCI DSS).
- Customization: On-premise deployments provide the flexibility to heavily customize the gateway to integrate deeply with existing internal systems, identity providers, and monitoring stacks.
- Resource Management: It requires internal teams to manage the underlying hardware, networking, and software stack, demanding significant operational overhead but offering complete sovereignty.
- Example: Solutions like ApiPark offer quick deployment options (e.g., a single command-line script), making on-premise setup feasible even for complex platforms.
- Cloud-based Deployment (SaaS or Managed Service):
- Ease of Use and Scalability: Cloud-based solutions (Software as a Service) abstract away infrastructure management entirely. Providers handle scaling, maintenance, and updates, allowing enterprises to consume the AI Gateway as a service. This model offers rapid deployment and virtually infinite scalability without worrying about underlying compute resources.
- Cost-Effectiveness: It often shifts capital expenditures to operational expenditures, with pricing typically based on usage, which can be cost-effective for varying workloads.
- Reduced Operational Overhead: Internal teams are freed from infrastructure management, allowing them to focus on core business logic and AI application development.
- Vendor Dependence: The trade-off is a degree of vendor lock-in and reliance on the cloud provider's security and compliance posture.
- Hybrid Deployment:
- Balance of Control and Flexibility: A hybrid model combines elements of both on-premise and cloud deployments. For instance, sensitive AI models or data might be managed by an on-premise AI Gateway, while less sensitive or high-volume general AI services leverage a cloud-based gateway.
- Gradual Migration: This approach allows organizations to gradually transition AI workloads to the cloud or integrate cloud AI services with existing on-premise systems, providing flexibility and risk mitigation.
- Complex Management: Managing a hybrid environment can introduce its own complexities in terms of networking, security policies, and unified monitoring across disparate environments.
Regardless of the chosen model, the ease of deployment is a significant factor. ApiPark, for example, emphasizes its capability for quick deployment in just 5 minutes with a single command line, making it highly accessible for rapid integration into existing infrastructures.
Microservices and API-First Principles: The Natural Fit
The AI Gateway is a natural and essential fit within a microservices and API-first architectural paradigm.
- Microservices Orchestration: In a microservices environment, applications are composed of many small, independent services. When these services need to interact with AI models, the AI Gateway acts as the dedicated orchestrator for all AI-related interactions. It prevents each microservice from having to implement its own AI integration logic, thereby promoting loose coupling and separation of concerns.
- Promoting Reusability and Modularity: By exposing a unified AI API, the gateway encourages the reuse of AI services across different microservices and applications. Instead of duplicating AI integration code in every service, developers simply call the gateway, enhancing modularity and consistency.
- API-First Design: Adopting an API-first approach means that APIs are treated as first-class products. The AI Gateway embodies this by centralizing the management, documentation, and consumption of AI services as well-defined APIs. It turns internal AI models and external LLMs into discoverable, consumable products within the organization. As an "API developer portal," ApiPark exemplifies this, allowing for centralized display and sharing of all API services, including AI capabilities, within teams.
Scalability and High Availability: Ensuring Uninterrupted AI Services
For mission-critical AI applications, the AI Gateway must be designed for extreme scalability and high availability.
- Cluster Deployment: To handle large-scale traffic and prevent single points of failure, AI Gateways typically support cluster deployment. This involves running multiple instances of the gateway behind a load balancer, distributing incoming requests and ensuring that if one instance fails, others can seamlessly take over.
- Performance Benchmarks: High-performance gateways are crucial. Solutions like ApiPark demonstrate impressive performance, capable of achieving over 20,000 TPS (Transactions Per Second) with modest resources (8-core CPU, 8GB memory) and supporting cluster deployment to handle massive traffic loads, rivaling the performance of industry standards like Nginx.
- Resilience Patterns: The gateway implements resilience patterns such as circuit breakers, timeouts, and automatic retries to prevent cascading failures to backend AI models. This ensures that transient issues with an AI service do not bring down the entire application.
- Auto-Scaling: Integration with cloud auto-scaling groups allows the gateway to automatically scale its instances up or down based on real-time traffic demand, optimizing resource utilization and cost.
Multi-Tenancy Support: Empowering Diverse Teams
In large enterprises, different departments, teams, or even external partners may need to consume AI services, often with their own independent configurations, access controls, and data. Multi-tenancy support within an AI Gateway addresses this need.
- Independent API and Access Permissions: A multi-tenant AI Gateway enables the creation of multiple isolated environments (tenants), where each tenant (e.g., a specific department or team) has its own independent applications, data configurations, and security policies.
- Shared Infrastructure, Reduced Costs: While tenants operate independently, they share the underlying gateway infrastructure and resources. This improves resource utilization, reduces operational costs, and simplifies management compared to deploying separate gateways for each team.
- Centralized Governance, Decentralized Operation: This model allows for centralized governance and oversight of AI consumption across the enterprise while enabling individual teams to operate autonomously within their defined boundaries. ApiPark specifically offers this feature, allowing the creation of multiple teams (tenants) each with independent applications, data, user configurations, and security policies, sharing underlying infrastructure to improve resource utilization and reduce operational costs.
Developer Experience (DX): Accelerating AI Adoption
A well-designed AI Gateway significantly enhances the developer experience, which is critical for accelerating the adoption of AI within an organization.
- Simplified Integration: By providing a unified and consistent API, developers are shielded from the complexities of integrating with diverse AI models, reducing cognitive load and development time.
- Comprehensive Documentation: Gateways often integrate with developer portals that provide auto-generated documentation for all exposed AI APIs, complete with examples, request/response schemas, and authentication instructions. ApiPark as an API developer portal facilitates this.
- API Service Sharing: Platforms like ApiPark allow for the centralized display of all API services, making it easy for different departments and teams to find and use the required AI services, fostering internal collaboration and accelerating project delivery.
- Self-Service Capabilities: Developers can often subscribe to APIs, view their usage metrics, and manage their API keys through a self-service portal, empowering them to work efficiently without constant administrator intervention.
Enterprise Value Proposition: The Strategic Imperative
The strategic integration of an AI Gateway delivers profound value across various facets of an enterprise:
- Accelerated AI Adoption: By simplifying integration and centralizing management, the gateway lowers the barrier to entry for AI, enabling more teams to leverage AI capabilities faster.
- Reduced Operational Complexity: It streamlines the management of diverse AI models, reducing the overhead associated with monitoring, updating, and securing disparate AI services.
- Improved Security Posture: Centralized authentication, authorization, and AI-specific security features significantly enhance the overall security of AI interactions, mitigating risks.
- Significant Cost Savings: Through intelligent routing, rate limiting, quota management, and detailed cost tracking, the gateway helps optimize AI expenditure and prevent budget overruns.
- Enhanced Data Insights: Comprehensive logging and analytics provide deep insights into AI usage patterns, model performance, and operational trends, informing better decision-making.
- Business Agility: The ability to seamlessly switch between AI models, experiment with new prompts, and rapidly deploy new AI features fosters greater business agility and innovation.
Ultimately, an AI Gateway like ApiPark becomes an indispensable layer that governs the entire AI lifecycle, transforming potential chaos into controlled efficiency. Its powerful API governance solution can enhance efficiency, security, and data optimization for developers, operations personnel, and business managers alike, solidifying its role as a strategic imperative for any enterprise serious about leveraging AI.
6. Practical Considerations and Best Practices
Implementing an AI Gateway effectively requires careful planning and adherence to best practices. From selecting the right solution to ensuring ongoing security and governance, these considerations are crucial for maximizing the benefits of this pivotal architectural component.
Choosing the Right AI Gateway: Making an Informed Decision
The market for AI Gateways and LLM Gateways is rapidly evolving, with various solutions offering different feature sets, deployment models, and support structures. Making the right choice involves evaluating several key factors:
- Open-source vs. Commercial Solutions:
- Open-source: Platforms like ApiPark, which is open-sourced under the Apache 2.0 license, offer flexibility, transparency, and often a vibrant community. They are ideal for organizations that want deep customization, avoid vendor lock-in, and have the internal expertise to manage and contribute to the codebase. While providing fundamental features, they might require more internal effort for advanced enterprise-grade functionalities.
- Commercial: Commercial products offer out-of-the-box advanced features, dedicated professional technical support, and often more robust SLAs (Service Level Agreements). They are suitable for enterprises requiring comprehensive solutions with less internal management overhead, particularly for mission-critical applications. Some open-source projects, including ApiPark, also offer commercial versions with advanced features and professional technical support for leading enterprises, providing a hybrid approach.
- Feature Set Comparison: Carefully assess the specific functionalities offered by each gateway. Does it support your current AI models (traditional ML, specific LLMs)? Does it offer advanced prompt management, intelligent routing, cost tracking, and security features tailored to your needs? Look for unified API formats, granular access control, detailed logging, and performance metrics crucial for your AI workloads.
- Scalability and Performance: Evaluate the gateway's ability to handle anticipated traffic volumes and its performance characteristics (latency, throughput). Benchmarks (e.g., ApiPark's 20,000 TPS) and support for cluster deployment are important indicators.
- Deployment Flexibility: Consider whether the gateway supports your preferred deployment model (on-premise, cloud, hybrid) and how easy it is to deploy and integrate into your existing infrastructure.
- Community and Documentation: A strong community around an open-source project or comprehensive documentation for a commercial product indicates good support, easier troubleshooting, and continuous improvement.
- Ecosystem Integration: How well does the gateway integrate with your existing observability tools, CI/CD pipelines, identity management systems, and cloud providers?
Security Best Practices: Fortifying Your AI Interactions
The AI Gateway is a critical choke point for all AI traffic, making its security paramount.
- Least Privilege Principle: Grant only the minimum necessary permissions to users and applications accessing AI services through the gateway. Restrict access to configuration, sensitive data, and management interfaces.
- Regular Security Audits: Conduct periodic security audits and penetration testing of the AI Gateway and its configurations to identify and remediate vulnerabilities proactively.
- Data Encryption: Ensure that all data in transit and at rest, especially sensitive data exchanged with AI models, is encrypted using strong cryptographic protocols (e.g., TLS for communication, AES-256 for data at rest).
- API Key and Token Rotation: Implement a robust lifecycle management system for API keys and authentication tokens, including regular rotation, secure storage, and immediate revocation upon compromise.
- Input Validation and Output Sanitization: Configure the gateway to perform rigorous input validation to prevent malicious data from reaching AI models and sanitize AI model outputs to prevent injection attacks (e.g., XSS) into client applications.
- Prompt Injection Protection: For LLMs, deploy specific guardrails and filtering mechanisms within the gateway to detect and mitigate prompt injection attempts, where attackers try to manipulate the LLM's behavior.
- Access Logging and Alerting: Ensure comprehensive logging of all access attempts, successful and failed. Configure real-time alerts for suspicious activities, unauthorized access attempts, or unusual traffic patterns.
Performance Tuning: Optimizing for Speed and Efficiency
Optimizing the performance of your AI Gateway is essential for responsive AI applications and cost efficiency.
- Network Latency Minimization: Deploy the gateway geographically close to both your client applications and your AI model endpoints to minimize network latency. Utilize CDN (Content Delivery Network) integrations if applicable.
- Resource Allocation: Allocate sufficient CPU, memory, and network resources to the gateway instances. Monitor resource utilization continuously and scale resources dynamically based on demand.
- Caching Strategy: Implement an intelligent caching strategy for frequently requested AI responses. Define clear cache invalidation policies to maintain data freshness.
- Connection Pooling: Optimize connection pooling settings to backend AI services to reduce the overhead of establishing new connections for every request.
- Efficient Logging: While comprehensive logging is vital, ensure that logging mechanisms are efficient and do not introduce significant overhead. Asynchronous logging or offloading logs to dedicated services can help.
- Gzip Compression: Enable Gzip compression for API responses where appropriate to reduce data transfer sizes and improve network performance.
Governance and Lifecycle Management: Structured AI Deployment
Effective governance ensures that AI services are managed systematically throughout their entire lifecycle.
- End-to-End API Lifecycle Management: The AI Gateway should be part of a broader API management strategy that covers the entire lifecycle of AI APIs – from design and development to publication, invocation, versioning, and eventual decommissioning. ApiPark assists with managing the entire lifecycle of APIs, helping regulate API management processes, traffic forwarding, load balancing, and versioning.
- Version Control for APIs and Prompts: Treat AI API definitions, prompt templates, and gateway configurations as code, managing them in a version control system (e.g., Git). This enables traceability, collaboration, and easy rollback.
- Standardized API Definitions: Enforce standardized API definition formats (e.g., OpenAPI/Swagger) for all AI services exposed through the gateway, promoting consistency and automated documentation.
- Policy Enforcement: Use the gateway to enforce organizational policies related to data privacy, security, cost, and usage across all AI services.
- Developer Portal: Provide a well-maintained developer portal that serves as a single source of truth for all AI APIs, enabling self-service discovery, subscription, and access for internal and external developers.
Monitoring and Alerting: Proactive Issue Detection
Robust monitoring and alerting capabilities are crucial for maintaining the health and performance of your AI Gateway and the AI services it orchestrates.
- Comprehensive Metrics Collection: Collect metrics on gateway performance (CPU, memory, network I/O), API traffic (request counts, latency, error rates per API/model), and AI-specific metrics (token usage, cost per inference).
- Centralized Logging: Aggregate logs from the gateway and backend AI services into a centralized logging system for correlation and analysis. ApiPark provides detailed API call logging, recording every detail of each API call, essential for tracing and troubleshooting.
- Proactive Alerting: Configure alerts for critical thresholds (e.g., high error rates, increased latency, excessive token usage, security anomalies) to notify operations teams immediately of potential issues.
- Dashboard Visualization: Create intuitive dashboards that provide a real-time overview of the AI Gateway's operational status and the performance of integrated AI services. ApiPark offers powerful data analysis capabilities, analyzing historical call data to display long-term trends and performance changes, which helps businesses with preventive maintenance.
- SLA Enforcement: Use monitoring data to ensure that AI services meet defined Service Level Agreements (SLAs) and identify areas for improvement.
By diligently applying these practical considerations and best practices, organizations can ensure that their AI Gateway becomes a stable, secure, high-performing, and strategically valuable asset, driving the successful adoption and scalable integration of Artificial Intelligence across the enterprise.
Conclusion
The journey into the burgeoning world of Artificial Intelligence, especially with the transformative capabilities of Large Language Models, is fraught with both immense promise and intricate challenges. As enterprises increasingly weave AI into the fabric of their operations, the need for a sophisticated, intelligent orchestration layer becomes unequivocally clear. The AI Gateway emerges not merely as an evolutionary step beyond the traditional API Gateway but as an indispensable architectural cornerstone designed specifically to navigate the complexities of modern AI integration.
We have traversed the landscape of AI integration, from understanding the inherent diversity of AI models and the unique complexities of LLMs to dissecting the extensive functionalities of an AI Gateway. This intelligent intermediary abstracts away the varied APIs, manages prompt engineering, provides advanced security measures, optimizes costs through intelligent routing, and offers unparalleled observability into AI workloads. The specialized LLM Gateway further refines these capabilities, meticulously addressing the nuances of context management, token optimization, and output moderation crucial for harnessing the full potential of generative AI.
Strategically integrating an AI Gateway into an enterprise architecture provides a multitude of benefits: it drastically simplifies integration for developers, accelerates AI adoption across diverse teams through multi-tenancy and API-first principles, bolsters security with granular access controls and AI-specific threat protection, and significantly optimizes operational costs and performance through intelligent resource management. Solutions like ApiPark exemplify this vision, offering an all-in-one open-source AI Gateway and API management platform that unifies AI invocation, streamlines API lifecycle management, and provides robust performance and detailed analytics. By centralizing governance and streamlining access, organizations can move from a chaotic, fragmented approach to AI consumption to a coherent, secure, and highly efficient ecosystem.
As AI continues to evolve at an astonishing pace, the role of the AI Gateway will only grow in prominence. It will become even more intelligent, adapting autonomously to changing model landscapes, optimizing performance in real-time, and pre-emptively mitigating risks. By embracing and strategically deploying an AI Gateway, enterprises are not just adopting a piece of technology; they are investing in a future where the immense power of AI is not just accessible, but seamlessly integrated, responsibly governed, and fully leveraged to unlock unprecedented innovation and competitive advantage. The future of AI is not just about powerful models, but about the intelligent infrastructure that enables their seamless integration and widespread impact.
Frequently Asked Questions (FAQs)
1. What is the fundamental difference between an API Gateway, an AI Gateway, and an LLM Gateway? A traditional API Gateway acts as a single entry point for client requests to backend services, providing basic routing, authentication, and rate limiting. An AI Gateway extends this by adding AI-specific functionalities like unified API interfaces for diverse AI models, intelligent routing based on model characteristics (cost, latency), prompt management, and AI-centric observability. An LLM Gateway is a specialized type of AI Gateway that focuses specifically on the unique challenges of Large Language Models, offering advanced features for context management, token optimization, prompt orchestration, and LLM-specific security guardrails.
2. Why can't I just integrate AI models directly into my applications without an AI Gateway? While direct integration is technically possible, it leads to significant complexities. Each AI model (especially from different vendors) has its own unique API, authentication, and data format. Direct integration requires developers to write bespoke code for each, leading to duplicated effort, increased maintenance overhead, vendor lock-in, and difficulties in managing costs, security, and performance at scale. An AI Gateway centralizes and abstracts these complexities, offering a unified interface and common management layer.
3. How does an AI Gateway help with cost optimization for AI services? An AI Gateway optimizes costs through several mechanisms: * Intelligent Routing: It can route requests to the most cost-effective AI model for a given task, dynamically switching providers based on pricing. * Rate Limiting & Quota Management: It enforces limits on usage per user or application, preventing accidental overspending. * Detailed Cost Tracking: It provides granular logging of usage (e.g., tokens used for LLMs), enabling accurate cost allocation and identifying areas for optimization. * Caching: By caching frequently requested AI responses, it reduces the number of calls to paid AI services.
4. What are the key security benefits of using an AI Gateway, especially for LLMs? An AI Gateway significantly enhances AI security by: * Centralized Authentication & Authorization: Enforcing security policies at a single point, including granular access control. * Data Sanitization & Input Validation: Protecting against malicious inputs to AI models. * Prompt Injection Protection: Implementing filters and rules specifically for LLMs to mitigate prompt injection attacks. * Output Moderation: Filtering out harmful, biased, or inappropriate content generated by generative AI before it reaches users. * Compliance: Helping organizations adhere to data privacy and security regulations by centralizing control over AI data flows.
5. Can an AI Gateway manage both cloud-based and on-premise AI models simultaneously? Yes, a robust AI Gateway is designed for deployment flexibility and can typically manage AI models deployed across various environments. Whether your AI models are hosted by cloud providers (e.g., AWS, Azure, Google Cloud), private cloud instances, or entirely on-premise, the AI Gateway acts as a unified facade. This capability is particularly useful for hybrid cloud strategies or for organizations that need to integrate both proprietary internal models and external commercial AI services.
🚀You can securely and efficiently call the OpenAI API on APIPark in just two steps:
Step 1: Deploy the APIPark AI gateway in 5 minutes.
APIPark is developed based on Golang, offering strong product performance and low development and maintenance costs. You can deploy APIPark with a single command line.
curl -sSO https://download.apipark.com/install/quick-start.sh; bash quick-start.sh
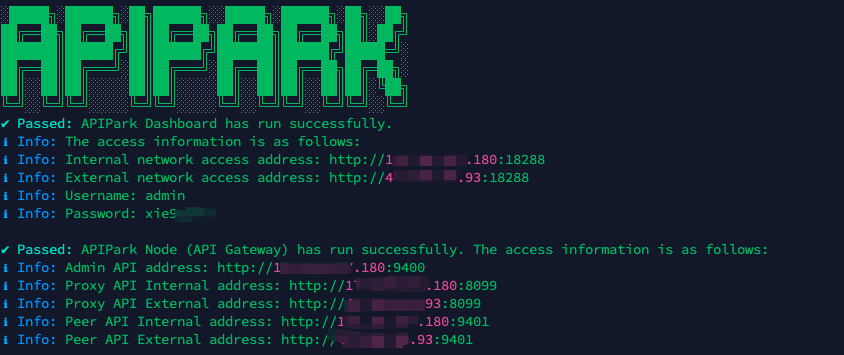
In my experience, you can see the successful deployment interface within 5 to 10 minutes. Then, you can log in to APIPark using your account.
Step 2: Call the OpenAI API.